tf-idf


TF(Term Frequency)-IDF(Inverse Document Frequency) from scratch in ...

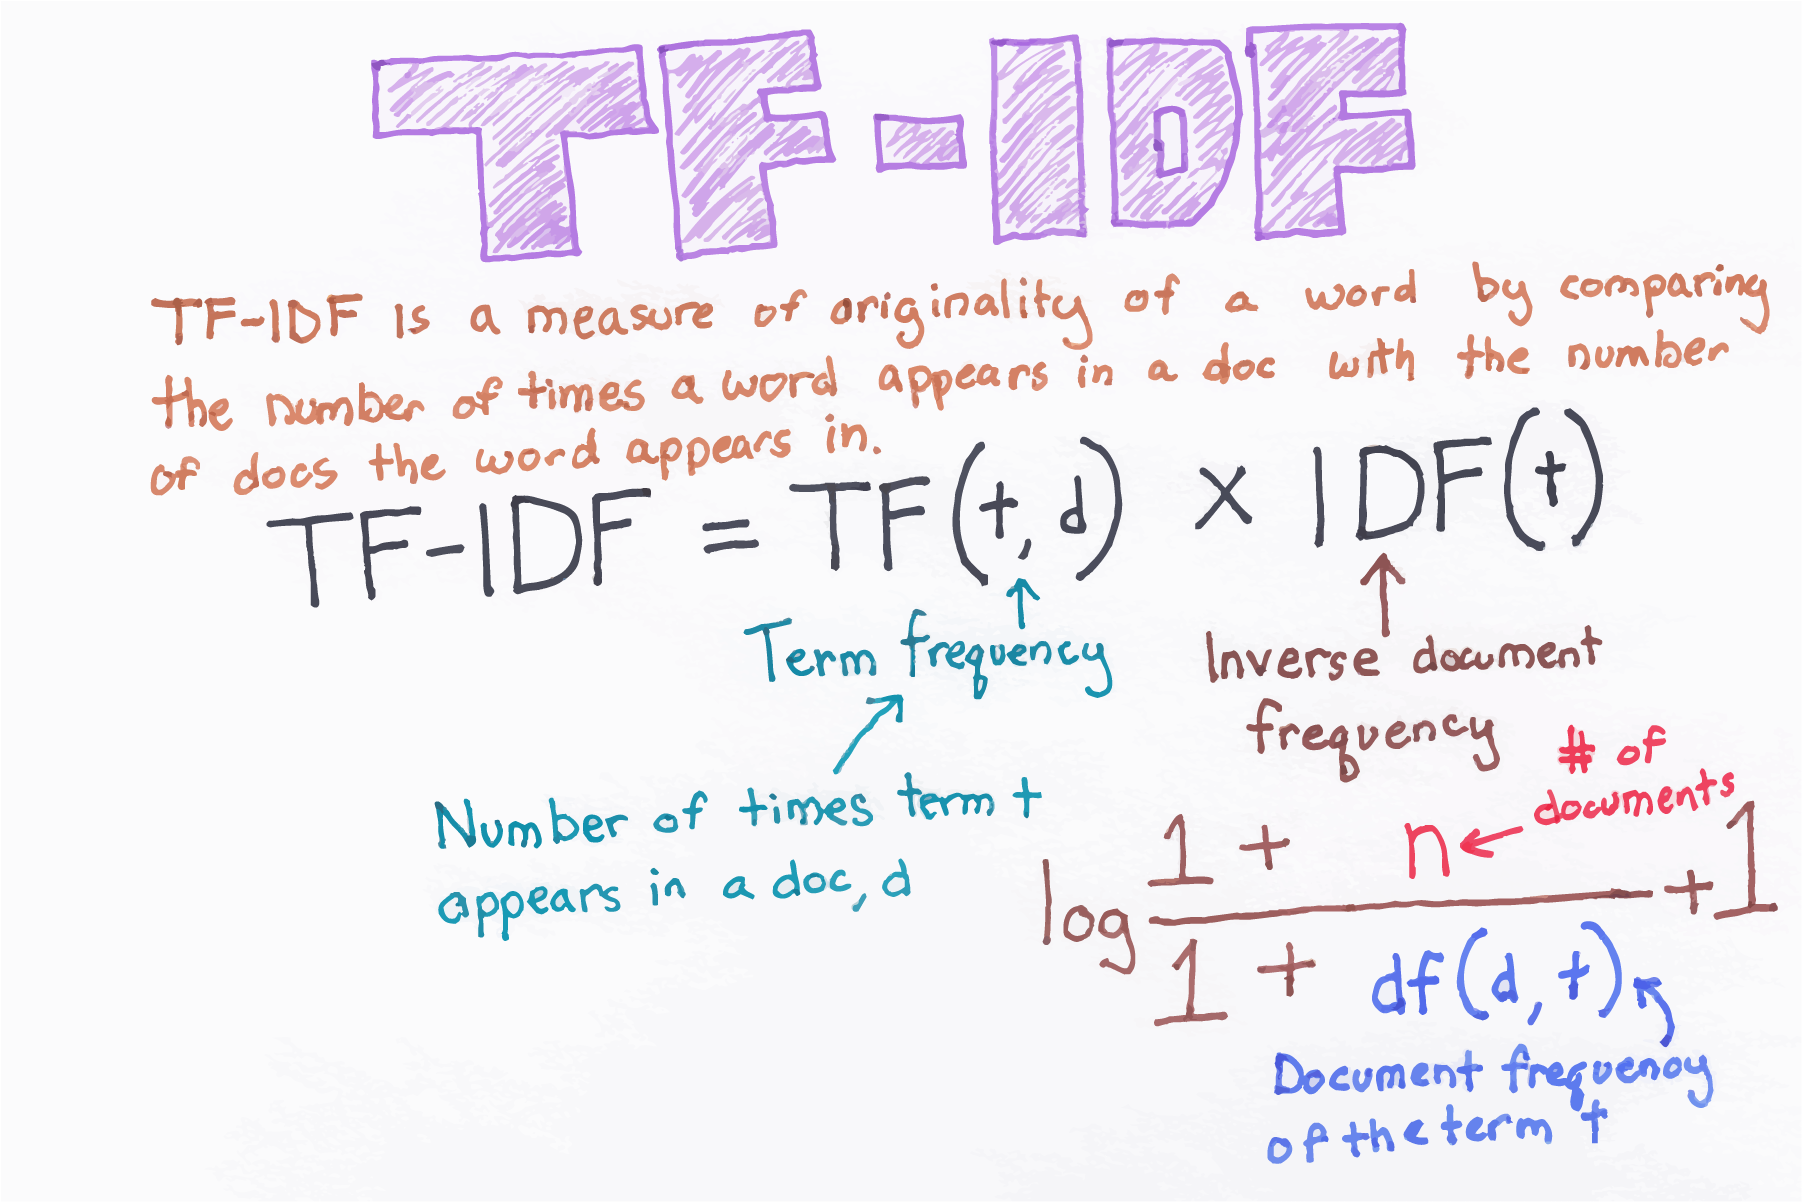
In information retrieval, tf–idf or TFIDF, short for term frequency–inverse document frequency, is a numerical statistic that is intended to reflect how important a word is to a document in a collection or corpus. It is often used as a weighting factor in searches of information retrieval, text mining, and user modeling. The tf–idf value increases proportionally to the number of times a word appears in the document and is offset by the number of documents in the corpus that contain the word, which helps to adjust for the fact that some words appear more frequently in general. tf–idf is one of the most popular term-weighting schemes today. A survey conducted in 2015 showed that 83% of text-based recommender systems in digital libraries use tf–idf.

Variations of the tf–idf weighting scheme are often used by search engines as a central tool in scoring and ranking a document's relevance given a user query. tf–idf can be successfully used for stop-words filtering in various subject fields, including text summarization and classification.

One of the simplest ranking functions is computed by summing the tf–idf for each query term; many more sophisticated ranking functions are variants of this simple model.

Term frequency
Suppose we have a set of English text documents and wish to rank which document is most relevant to the query, "the brown cow". A simple way to start out is by eliminating documents that do not contain all three words "the", "brown", and "cow", but this still leaves many documents. To further distinguish them, we might count the number of times each term occurs in each document; the number of times a term occurs in a document is called its term frequency. However, in the case where the length of documents varies greatly, adjustments are often made (see definition below). The first form of term weighting is due to Hans Peter Luhn (1957) which may be summarized as:

The weight of a term that occurs in a document is simply proportional to the term frequency.

Inverse document frequency
Because the term "the" is so common, term frequency will tend to incorrectly emphasize documents which happen to use the word "the" more frequently, without giving enough weight to the more meaningful terms "brown" and "cow". The term "the" is not a good keyword to distinguish relevant and non-relevant documents and terms, unlike the less-common words "brown" and "cow". Hence an inverse document frequency factor is incorporated which diminishes the weight of terms that occur very frequently in the document set and increases the weight of terms that occur rarely.

Karen Spärck Jones (1972) conceived a statistical interpretation of term-specificity called Inverse Document Frequency (idf), which became a cornerstone of term weighting:

The specificity of a term can be quantified as an inverse function of the number of documents in which it occurs.
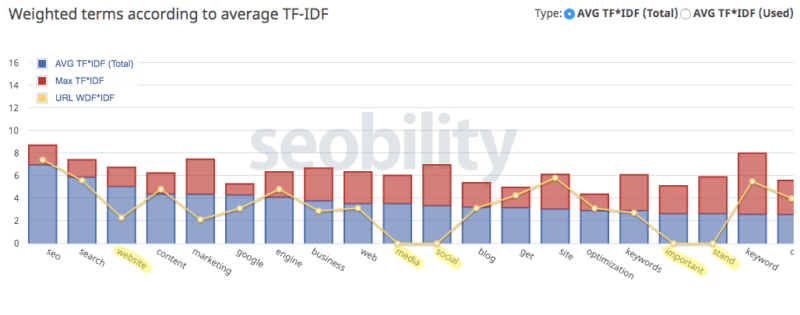
TF-IDF: The best content optimization tool SEOs aren't using
Implementing a TF-IDF (term frequency-inverse document frequency ...

Comments

Popular posts from this blog

Artificial Neural Network

Artificial neural networks (ANN) or connectionist systems are computing systems vaguely inspired by the biological neural networks that constitute animal brains. The data structures and functionality of neural nets are designed to simulate associative memory. Neural nets learn by processing examples, each of which contains a known "input" and "result," forming probability-weighted associations between the two, which are stored within the data structure of the net itself. (The "input" here is more accurately called an input set, since it generally consists of multiple independent variables, rather than a single value.) Thus, the "learning" of a neural net from a given example is the difference in the state of the net before and after processing the example. After being given a sufficient number of examples, the net becomes capable of predicting results from inputs, using the associations built from the example set. If a feedback loop is prov...

Which AWS Certifications Exist for AI? A Practical Map

 If you want to prove you can work with AI on AWS, the certification catalog can feel crowded. This post gives you a map: which credentials are aimed at AI, who each one is for, what the exams look like, and in which order a sensible person would take them. Every figure below comes from the official AWS certification pages as they stood on 25 October 2026, so always double-check the live pages before you book anything. The short version Two certifications are built squarely around AI on AWS, and they sit at opposite ends of the difficulty scale: AWS Certified AI Practitioner (AIF-C01) is the foundational, concept-level exam. AWS Certified Generative AI Developer – Professional (AIP-C01) is the advanced, build-it-in-production exam. Around them sits a ring of neighbouring certifications that make good stepping stones, plus a newer business-focused AI credential and a set of hands-on "Demonstrated" credentials. At a glance Detail AI Practitioner GenAI Developer ...

Project: Heartbeat computing

In computer science, a heartbeat is a periodic signal generated by hardware or software to indicate normal operation or to synchronize other parts of a computer system. Usually, a heartbeat is sent between machines at a regular interval in the order of seconds; a heartbeat message. If the endpoint does not receive a heartbeat for a time—usually a few heartbeat intervals—the machine that should have sent the heartbeat is assumed to have failed. Heartbeat messages are typically sent non-stop on a periodic or recurring basis from the originator's start-up until the originator's shutdown. When the destination identifies a lack of heartbeat messages during an anticipated arrival period, the destination may determine that the originator has failed, shutdown, or is generally no longer available. Heartbeat messages may be used for high-availability and fault-tolerance purposes.